One API for every model
Chat Completions, the Anthropic Messages API and the Responses API, plus embeddings and transcription, all with the same key.
03 Serve $ hyai models
Shared per token, or running for you alone, from European data centres.
 GLM
 DeepSeek
 Qwen
 Kimi
 Mistral
 Llama
 gpt-oss
 Gemma
 Loes
 Nemotron
 Claude Code
 Codex
 OpenCode
 Cursor
 Cline
Loes
OpenAI SDK
 Anthropic SDK
What it does
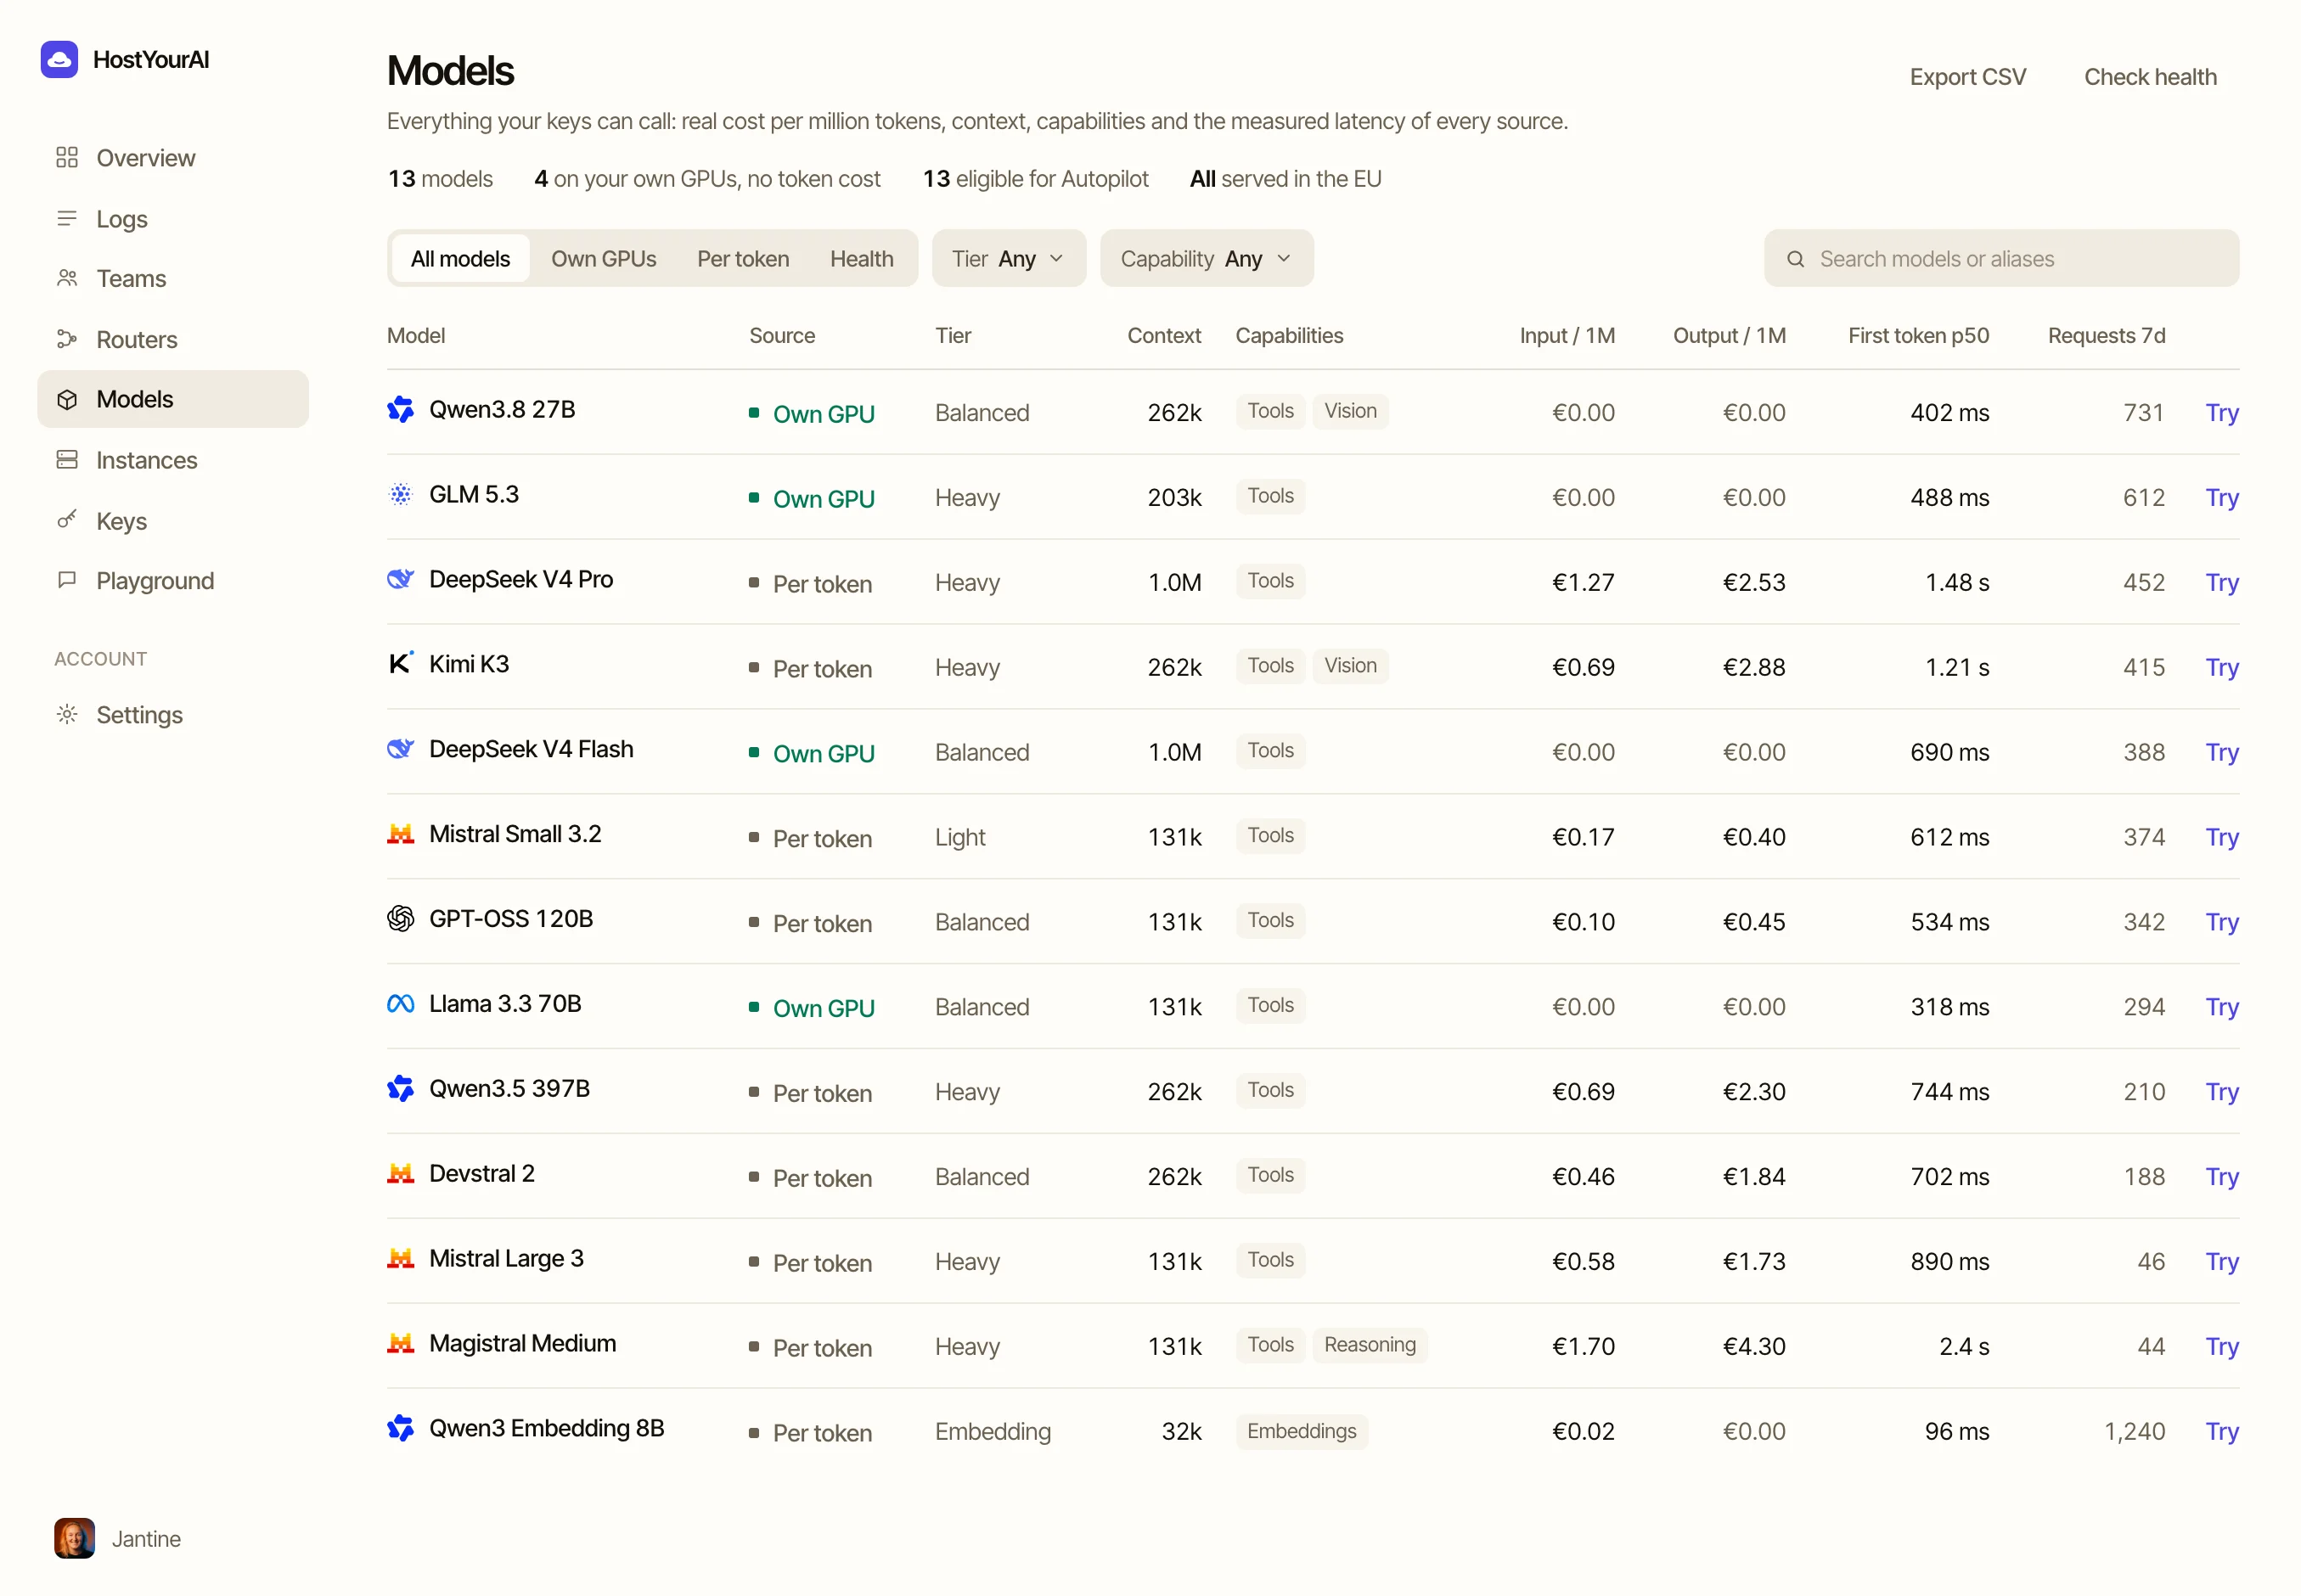
The model garden lists the open models you can call right now. Shared models run per token on GPUs in Europe: you pay for what you use and there is no machine to manage. Every model has its own page with its context length, its price per million tokens and a quality score.
When a model has to work for you alone, run it on a dedicated GPU. You create and delete it yourself, in the dashboard or through the API, and you pay per GPU minute while it runs. A private connection can keep its port closed to the public internet.
One model name can have several sources behind it. The router sends each request to a source that is healthy and fast, keeps a conversation on the machine that holds its cache, and moves on when a machine slows down.
Read more
Chat Completions, the Anthropic Messages API and the Responses API, plus embeddings and transcription, all with the same key.
Repeated prompt prefixes are billed at a lower rate automatically. You send nothing extra.
Every model carries a Bench score from public benchmarks, marked as measured or estimated, and the rankings show measured speed per model.
Serve a model from Hugging Face or your own finetune on a dedicated GPU, booted with the official vLLM recipe for that model.
Every model in the model garden that shows as available. We add new open models after we have tested them.
When the work needs a model nobody else runs, a guaranteed speed or full isolation. For most teams shared per token stays cheaper until the volume gets very large.
Yes. Set the base URL to https://hostyourai.com/api/v1 and use your HostYourAI key. The Anthropic SDK works the same way.
Start with one layer and add the others when the work asks for it. They share one key, one balance and one Activity view.
One key gives you every model in the garden. Top up credits and pay per token, without a subscription.